Agent Credential and Secret Storage in Persistent VMs
Unpredictable agent behavior breaks every existing credential storage pattern.
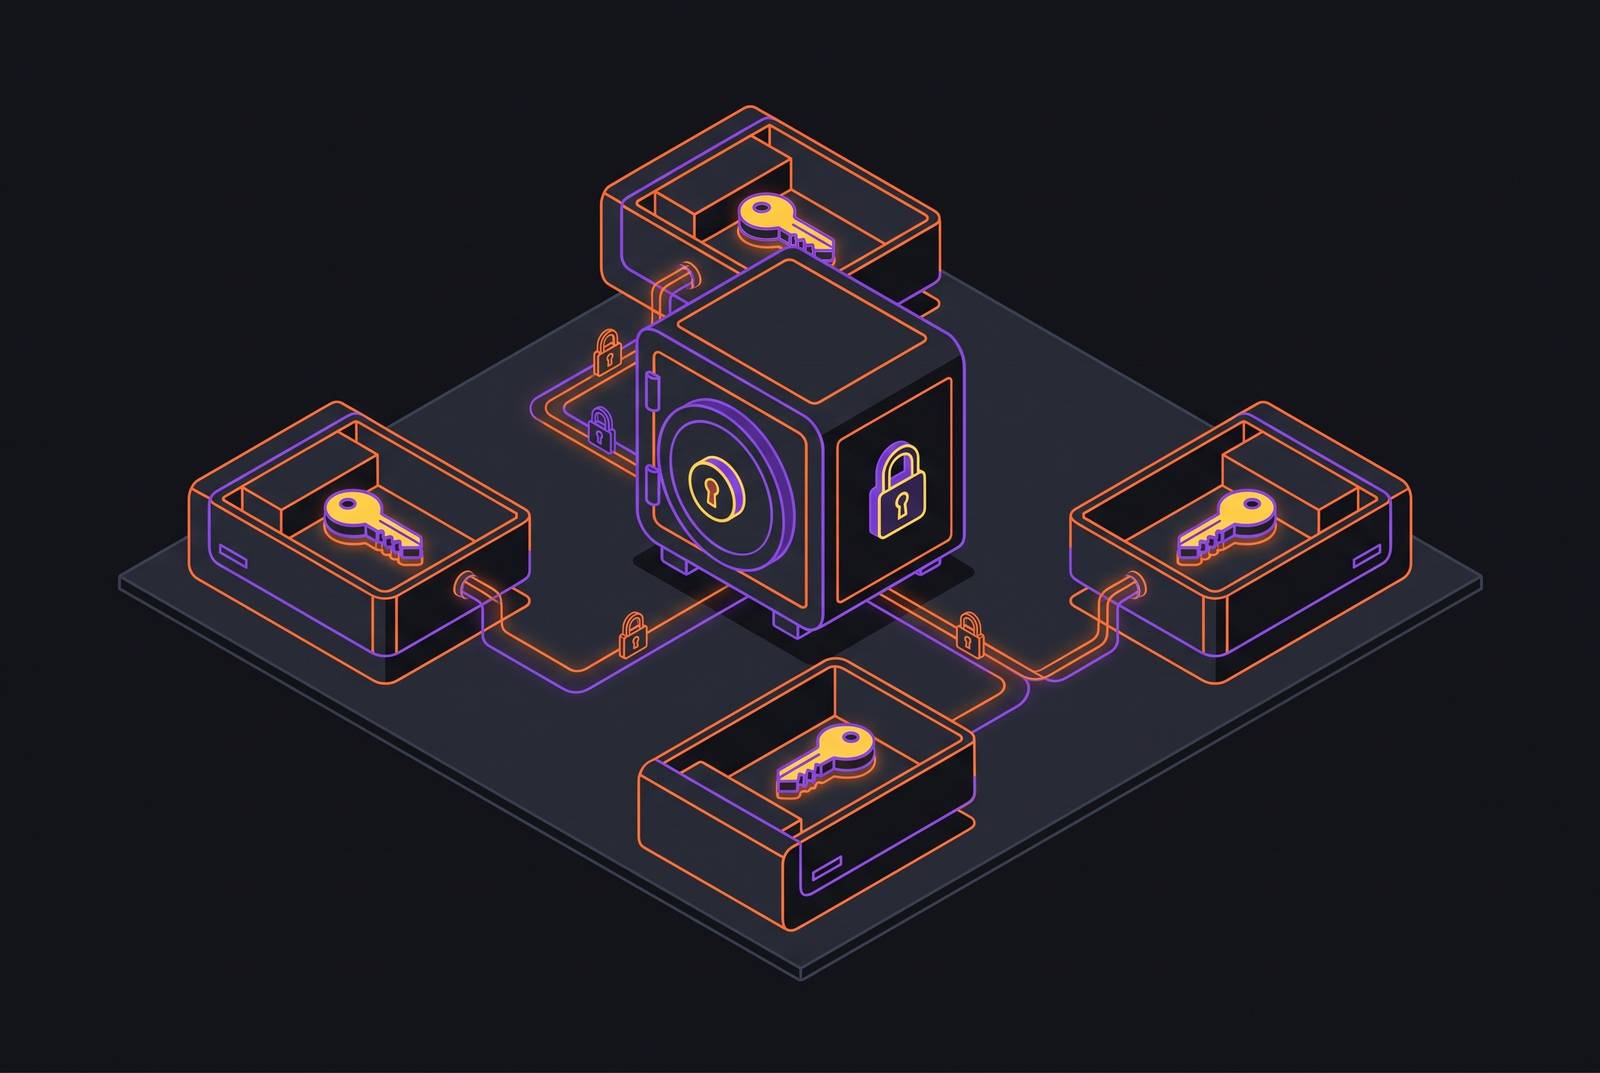
An AI agent decides at runtime which tools to call, and that single fact breaks every credential pattern built for software that behaves predictably. A coding agent might need GitHub tokens, cloud provider keys, and LLM API keys all within one session, and it may need none of them in the next run, depending on what the task in front of it requires. Descope's 2026 analysis names this behavioral unpredictability as the quality that separates agent credential management from both human identity and traditional machine identity: a human logs in once and inherits access through group membership, and a traditional service account calls the same endpoint with the same credential in the same pattern every time. An agent does neither. A single workflow might have it query a database, draft an email, schedule a meeting, and file a ticket, each action demanding a different permission against a different system, decided in the moment.
That unpredictability multiplies credential volume faster than any human governance process can track. One developer working with an AI coding assistant can create a dozen authenticated identities in an afternoon, each with its own key, each written to disk somewhere. The fan-out compounds from there: an assistant declares several MCP servers, and each one holds a separate credential to a separate production system, so the identity count multiplies at every hop rather than growing in step with headcount the way it did for two decades.
Agents also open a credential exfiltration path that human-operated software never had: prompt injection. A vulnerability disclosed in LangChain Core in December 2025, tracked as CVE-2025-68664 with a CVSS score of 9.3, let an attacker inject prompts that triggered the serialization and deserialization system into resolving specific environment variables as secrets. Where the secrets_from_env option was enabled, that meant credentials stored in those variables could be exposed to an attacker who never touched the underlying infrastructure at all, only the text the agent was asked to process.
Two incidents show what happens once that exposure turns into action. When multiple agents share a service account, an individual agent's behavior becomes unattributable: if one agent takes a destructive action, the audit trail shows which account was used but not which agent acted, and revoking the misbehaving one means revoking all of them. In March 2026, an internal AI agent at Meta posted an error-filled response to an internal forum without the requesting engineer's approval. Another employee followed the incorrect advice, and sensitive data was exposed in a Sev-1 incident. The agent had the scope to act, so it acted, with no consent step in between, and the question these incidents raise is how the environment an agent runs in should be built so that the patterns which made both incidents possible become impossible.
How the dominant anti-patterns embed credentials into agent runtimes
Three credential anti-patterns dominate production agent deployments today, and each one is a structural property of how agents get deployed, not a lapse in developer discipline.
The first is the unscoped, static API key, sitting in an environment variable or a config file. Descope identifies this as the default model in early MCP deployments: no expiration, no environment isolation, no tool-level scoping, and the same level of access whether the agent is running a routine read or a destructive overwrite. An environment variable grants a credential to everything running on the machine and keeps no record of who read it. The secret ends up in plaintext across config files, environment files, and shell histories, available to any process that happens to share the host.
The second is scope inheritance: an agent that takes on the user's full session, including every permission the user holds, whether or not the agent's task requires it. Nothing separates what the user actually authorized from what the agent decided to do on its own initiative, which is precisely the gap that let the Meta agent act without the requesting engineer's consent.
The third is the credential hardcoded directly into an agent configuration, or typed into a prompt, where it persists in chat history or agent memory indefinitely. These are the same habits that made .env files the leading source of credential leaks in traditional software, now replicated inside agent workflows at a faster pace.
The MCP ecosystem has made the config-file version of this problem worse at scale. Static secrets in environment variables are the dominant anti-pattern across production MCP deployments, and thousands of secrets are regularly exposed in MCP config files by developers who are following the official documentation exactly as written. A single hardcoded key shared across agent instances compounds all three patterns at once: context from one user's session bleeds into another user's queries, and rotating the key takes down every instance still depending on it.
What ties all three together is that the credential sits in the agent's runtime environment as a static artifact. It persists past the task that needed it, it's readable by anything else running on the same machine, and it leaves no trail when something reads it. None of this is a developer failing to follow best practice. It's the rational output of deployment substrates that offer no better place to put the secret.
Why stateless, shared runtimes leave the credential problem architecturally unsolved
The anti-patterns above exist because the runtimes agents are deployed into provide no natural trust boundary around a single agent's secrets. A container, a serverless function, a shared kernel environment: in each case, every agent running on that host shares the same kernel code paths with every other tenant on it. A single kernel vulnerability can travel laterally across every one of them. Secrets injected as environment variables are visible to any process with access to the process table or to /proc, which makes isolation a configuration option.
Containers share the host kernel, so one kernel bug reaches every neighbor on that host, because the isolation boundary is a namespace rather than a hardware boundary, and grafting a vault integration onto a stateless function reduces how much gets exposed but doesn't move the trust boundary anywhere. The agent is still running in a shared kernel environment where a compromised neighbor can reach the same memory space, and the credential fetched from the vault still has to live somewhere in that runtime at the moment it's used.
Giving every agent a unique, revocable identity, the baseline non-human-identity practice, runs into a hard limit in shared runtimes at scale. Creating a unique identity per agent instance means the identity count grows exactly as fast as agent instances are spawned, and a shared kernel means none of those identities is ever truly isolated from the others sharing it. Autonomous provisioning makes the problem worse before it gets better: getting a credential typically requires a human to open a browser, verify an email, generate a key, and paste it into an environment variable, which is impossible at step one for an agent running unattended. A stateless function, in any case, has no home to store what it would self-provision even if it could.
The fix for this isn't a more sophisticated vault integration layered on top of the same shared substrate. It requires an environment that is isolated and persistent by construction, where the boundary around the virtual machine itself does the work that policy was being asked to do.
How a persistent, isolated micro-VM changes the trust boundary for credential storage
When each agent lives in its own persistent micro-VM with its own kernel, the credential storage problem is solved architecturally rather than through policy. The VM boundary becomes the trust boundary itself, not a rule applied on top of a runtime that was never built to enforce it.
Firecracker's isolation model is what makes this different from a container. Each microVM runs its own independent Linux kernel, so two sandboxes share no kernel code paths whatsoever. A kernel vulnerability that would propagate across every tenant on a shared host has nothing to propagate across here. Firecracker retains only the virtual devices necessary to run Linux workloads, and a jailer process layers chroot, cgroup, and seccomp restrictions on top of hardware virtualization, which is the isolation layer appropriate for adversarial or untrusted third-party code, exactly the category an autonomous agent executing arbitrary instructions falls into. This is the same isolation model that runs AWS Lambda at scale, with the guarantee proven at production volume.
Persistence changes what that VM is able to hold onto. A micro-VM with a persistent disk can store credentials in an encrypted file, a local secrets store, or a provisioned key that survives sleep and redeploy, with no human needed to re-inject the secret on every cold start. Isolation changes what the VM protects: secrets written into the VM's filesystem or memory are inaccessible to any other tenant's agent, as a property of the architecture.
The per-agent VM model maps directly onto the non-human identity practice of giving every agent instance its own unique, revocable identity. One VM equals one identity equals one credential namespace, with nothing shared between them by default. That also resolves the audit trail problem that shared service accounts create: access to the secrets inside a given VM is attributable to that agent's identity alone, not to an account five other agents might also be using. Which agent did what becomes a structural fact about where the credential lived, not a logging problem.
Snapshot-restore scheduling and credential lifecycle
Snapshot-restore scheduling is usually framed as a cost optimization, but it produces a credential lifecycle model that stateless functions have no way to replicate. Secrets can be scoped to a VM's active window and expire cleanly the moment that VM hibernates, rather than sitting live in memory indefinitely waiting for someone to rotate them.
The mechanism works by booting a microVM to a ready state, snapshotting its memory and block device state, and restoring from that snapshot on demand. That turns the cost of keeping a warm pool idle into the cost of storing a snapshot instead. Restore latency under 30 milliseconds means a VM can be suspended the moment an agent goes idle and brought back the instant work arrives, without the agent or its credential state sitting resident in memory for however long it was waiting. The security consequence follows directly from the speed: a credential no longer has to live inside a continuously running process to be available when needed. It can be restored into a fresh memory space on demand, which shrinks the window a live credential spends resident and attackable to the span of the task itself.
Fast creation turns the VM into a credential hygiene tool on its own. If spinning up a fresh isolated VM takes under 200 milliseconds, that VM can be treated as disposable, one per task or one per job. A fresh VM per agent run means no credential state accumulates across tasks that have nothing to do with one another, and cross-contamination between sessions becomes structurally impossible rather than something a developer has to remember to clean up after the fact.
This also reframes the usual argument for keeping a shared warm pool running. The reason teams keep one alive is latency: cold starts are too slow to tolerate on a per-request basis. Once per-agent VMs can be restored in under 200 milliseconds, that economic case for sharing a runtime, and sharing its credential namespace along with it, mostly disappears. What gets snapshotted is defined precisely, and what gets restored is defined precisely alongside it. A secret that shouldn't persist across sessions simply isn't part of the snapshot, which makes the snapshot boundary a credential boundary as much as it is a performance one.
The three credential delivery models that work inside a persistent VM runtime
A persistent VM runtime supports three distinct ways to get credentials to an agent, and the right choice depends on whether the agent runs continuously, handles one-off tasks, or operates as part of a multi-agent pipeline, not on which vault vendor a team happens to prefer.
The first model is persistent vault access with scoped runtime fetch. The agent authenticates to a secrets vault at runtime and pulls a scoped, time-limited credential on demand. The relationship with the vault persists across sessions, but the credential itself is short-lived. HashiCorp Vault's dynamic secrets engine is the most established implementation of this pattern: instead of storing a static database password, Vault generates a temporary credential with a configurable TTL the moment the agent requests access, and the credential is automatically revoked once that TTL expires. Another vendor offers a self-hostable alternative covering the same pattern, with native integrations across major cloud and infrastructure destinations and SDKs for Python, Node.js, and Go built for agent framework integration. It also adds MCP endpoint governance, giving teams centralized policy control over how agents reach the tools behind those endpoints. This model suits agents that run continuously, touch many services, and need credential rotation handled automatically.
The second model is ephemeral credential handoff through self-destructing delivery. Here the credential arrives through a one-time channel, a self-destructing link or a temporary endpoint, that ceases to exist the moment the agent consumes it. There's no vault relationship to maintain and no standing access left behind to revoke later, which suits agents handling ad-hoc tasks where setting up a persistent vault integration would be more infrastructure than the job warrants.
The third model applies inside multi-agent pipelines, where credentials need to pass from one agent to the next as a task moves through a sequence of specialized steps without ever being pooled into one shared secret store that every agent in the pipeline can read from. Each of the three models answers a different question about how long an agent needs access and how many other agents share its task, and the persistent, isolated VM is what makes all three viable in the same runtime rather than forcing every agent into whichever pattern the infrastructure happens to support.